Chapter 5.6 follows chapter 5.5, Purpose of the hidden tier, and precedes chapter 5.7, The chained task sequences, within part 5, the task library.
The scoring phase turns cell results into a disposition, the recorded outcome of the cell. The harness checks the visible tier, the tests exposed to the agent, then checks hidden results and the full suite. It records the result for later analysis. source: operations/site-ia/A6-page-briefs.md, section T5
5.6.1 Scoring contract of the maintenance-task suite
The scoring contract is stored in 1. Harness/config/scoring_contract.json. It defines four states for a test result: pass, fail, not_run, and invalid.
source: 1. Harness/config/scoring_contract.json, key score_states
The contract defines seven invalidity conditions. A cell is invalid when visible output is missing. It is invalid when hidden scoring output is missing. It is invalid when token usage data is missing. It is invalid when the reproducibility manifest is missing. It is invalid when the transcript contains multiple models. It is invalid when the hidden scorer is missing. It is invalid when the shell is unavailable.
source: 1. Harness/config/scoring_contract.json, key invalid_if
The contract also specifies the full-suite regression comparison. The scorer compares the full-suite result with a baseline pass set and records regressions introduced. The baseline comes from compute_or_load_baseline.
source: 1. Harness/config/scoring_contract.json, key full_suite_regression; 1. Harness/scripts/score_cell.py, function compute_or_load_baseline
The contract specifies the flaky rerun rule. When the agent result and the harness result disagree, the harness reruns the visible tests three times and records the resulting flaky pass state.
source: 1. Harness/config/scoring_contract.json, key flakiness_rerun; 1. Harness/scripts/score_cell.py, function _flaky_rerun_n at line 80
5.6.2 Scoring sequence of the maintenance-task suite
The visible tier is run from the agent-visible test set. The harness repeats that check through visible_step(). Hidden checks then run outside the agent’s view. The full suite follows through full_suite_step(). Their results feed the correctness gate and the overall score.
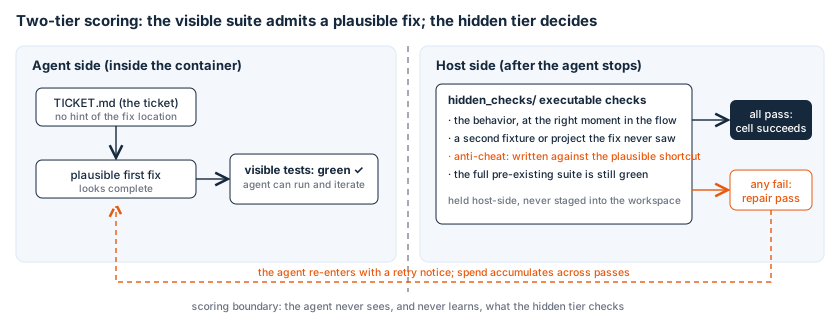
Two-tier scoring separates visible tests from hidden checks before the cell decision.
Figure D-T5-2. The scoring steps show visible checks, hidden checks, full-suite comparison, flakiness handling, and the recorded cell result in one ordered flow.
%% figure D-T5-2
flowchart LR
  subgraph g1[" "]
    n1["The scoring steps show visible checks<br/>hidden checks<br/>full-suite comparison<br/>flakiness handling"]
  end
  subgraph g2[" "]
    n2["the recorded cell result in one ordered flow"]
  end
  n1 --> n2
source: operations/site-ia/A3-diagram-specification.md
source: operations/site-ia/A6-page-briefs.md, section T5
Scoring steps from test execution to the recorded result.
The visible and hidden results both contribute to the correctness gate. The full-suite result contributes regression information. The scorer records each result in the summary file.
5.6.3 Outcome mapping of the maintenance-task suite
The scorer maps whether required checks pass and whether results are usable to a disposition. A successful cell passes the required checks. When the maximum number of permitted attempts is reached, the scorer records failure because another attempt is unavailable. When the maximum permitted token use is reached, it records failure because the resource allowance is exhausted. If a cell causes an external effect, the scorer records an external effect. If the task surface is absent, the outside scorer records that absence. If a record fails a validity check, the scorer records that failure.
Figure D-R4-3. The outcome branches from a completed cell record to success, ceiling failure, contamination, substrate absence, or invalid record.
%% figure D-R4-3
flowchart LR
  n1["The outcome branches from a completed cell record to success<br/>ceiling failure<br/>contamination<br/>substrate absence"]
  n2["or invalid record"]
  n1 --> n2
source: operations/site-ia/A3-diagram-specification.md
source: operations/site-ia/A6-page-briefs.md, section T5
Outcome mapping for the cell scorer.
When the substrate is absent, the outside scorer records substrate absent because the scorer cannot run the checks. That outcome is excluded from primary analysis. An invalid record is also excluded. The other recorded dispositions follow the analysis rules.
source: 1. Harness/scripts/rescore_tiered.py; 6. Metrics/metric_definitions.md
5.6.4 Recorded outcomes of the maintenance-task suite
The worked cell stores results in scoring_summary.json. Its score_states object contains five states: visible, hidden, full_suite, correctness_gate, and overall.
source: the worked cell’s scoring_summary.json, key score_states with visible, hidden, full_suite, correctness_gate and overall
The same summary records passes, visible_pass, hidden_pass, full_suite_pass, regressions_introduced, flaky_pass, and valid_for_primary_analysis. These fields preserve the checks used by the scorer and the decision passed to analysis.
Figure D-T5-4. The baseline pass set shows the pristine full-suite results beside the current cell results, with their difference producing the regression record.
%% figure D-T5-4
flowchart LR
  subgraph g1[" "]
    n1["The baseline pass set shows the pristine full-suite results beside the current cell results<br/>their difference producing the regression record"]
  end
source: operations/site-ia/A3-diagram-specification.md
source: operations/site-ia/A6-page-briefs.md, section T5
Baseline pass set comparison for regression recording.
The baseline is loaded by compute_or_load_baseline and used for the full-suite comparison. The package retry data remains in each package’s retry_feedback.json.
5.6.5 Retry notice of the maintenance-task suite
A retry notice, a message naming the unmet requirement for the next attempt, is generated by 1. Harness/scripts/gen_retry_feedback.py. It reads the task requirements and hidden checks, maps a failed check to its requirement, and writes the package’s retry_feedback.json. The notice names only the unmet requirement.
source: 1. Harness/scripts/gen_retry_feedback.py; 1. Harness/scripts/lint_retry_feedback.py; 1. Harness/scripts/rescore_tiered.py
The lint script checks the mapping before the rescorer uses it. The notice passes between attempts as feedback rather than changing the recorded score for the completed cell.
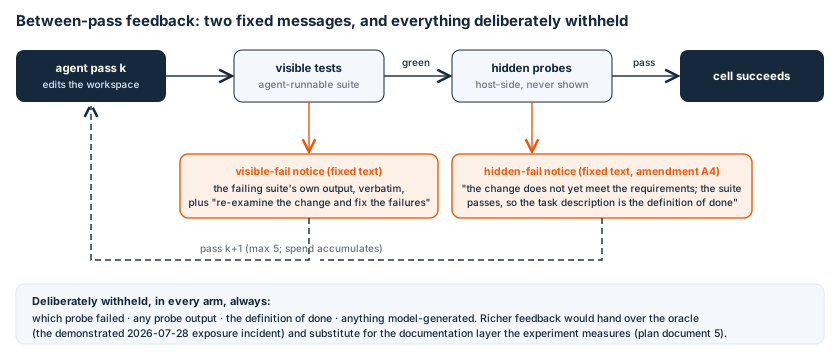
Feedback between passes through a focused retry notice.
5.6.6 Parser defect of the maintenance-task suite
The parser read test output by looking for result markers. A test name containing a space was split at that space, so the parser did not retain the complete test name. The affected result could not be matched and the cell could be marked invalid.
source: 1. Harness/scripts/score_cell.py, function visible_step() at line 728 and function full_suite_step() at line 783
The defect was found during review of the parser behavior. The repair kept spaces within test names while extracting the result. The affected cells were rescored, and the corrected outcomes were recorded.
source: 1. Harness/scripts/score_cell.py, functions visible_step() at line 728 and full_suite_step() at line 783